Drawings, designs and supplier data
Ask questions of CAD exports, specs and supplier files. Find every drawing that references a part. Route incoming documents to the right engineer.
A sealed AI appliance on NVIDIA DGX or Apple silicon, pre-loaded with five products that work over your own documents, drawings and records. Built, secured and operated by Periscope. Live in 30 days.
Most companies have a policy that says company data stays out of public AI. Almost none can enforce it, so the most valuable work stays manual. DeepSilo is for that work.
Ask questions of CAD exports, specs and supplier files. Find every drawing that references a part. Route incoming documents to the right engineer.
Summarise, classify and search records without a single byte leaving the practice. Audit trail of who asked what, for the compliance file.
Grounded answers from the contract set, code search across private repositories, drafting with the firm's own precedents. Nothing trains anyone else's model.
A shared workspace where teams ask, draft and decide over the same knowledge base, with roles and an audit trail.
Answers grounded in your documents, every answer cited to the page it came from.
Classifies and routes incoming documents to the right team and system, with the rules you set.
Questions about drawings, photos and scans, answered from the image itself.
Scanned pages become searchable text inside the silo, with sensitive fields tagged for policy.
Vectors plus a knowledge graph over your documents, and domain-tuned models on the GPU. Every product reads the same base, so an answer in RAG Chat, a route in DocSort and a drawing in Vision Chat agree.
Every tier ships sealed, pre-loaded with the five products, behind a WatchGuard perimeter, and operated by Periscope until your team takes over. Prices are fixed fees including hardware; operation is a monthly line.
AMD Ryzen AI Max+ 395 mini PC, for a team of up to 10.
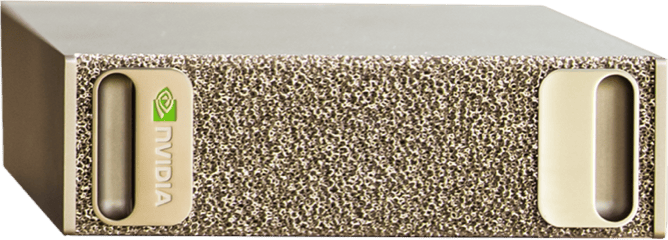
NVIDIA DGX Spark · GB10, for a team of up to 25.
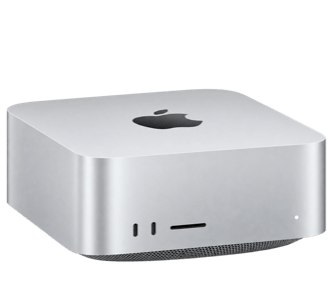
Mac Studio · M3 Ultra · MLX, for a team of up to 50.
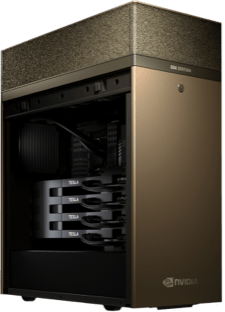
NVIDIA DGX Station · GB300, for a department of 100–500.
NVIDIA DGX B200/B300 or AMD Instinct, for enterprise and government, 500+.
Specs quoted from the vendors with "up to"; speeds are measured in the Periscope lab and vary by model and quantisation. Dubai AI Festival pricing applies to builds reserved by 30 November 2026. Prices are fixed-fee list prices and may change; your written sizing governs.
Not sure which? Size it in a minuteOpen-weight models we ship today, with the memory they need at 4-bit and the licence you would be accepting. The list is refreshed monthly; the speed of your chosen model is measured in the lab before your build ships.
70B-class dense, or 30B-class mixture-of-experts
120B mixtures, 70B fine-tuning, 400B-class when linked
DeepSeek-class 671B mixtures at 4-bit, inference only
1T-class, seven isolated GPU instances, fine-tuning at scale
| Model | Maker | Size | ≈ Memory, 4-bit | Smallest DeepSilo | Licence | Why we pick it |
|---|---|---|---|---|---|---|
| Llama 3.3 70B | Meta | 70B dense | ≈ 44 GB | Mini (at the limit) | Llama 3.3 Community | The default workhorse for grounded answers and drafting; the broadest tooling support. |
| gpt-oss-120b | OpenAI | 117B MoE · 5.1B active | ≈ 65 GB | Spark | Apache 2.0 | Ships in MXFP4 with adjustable reasoning effort; strong instruction following. |
| Qwen3-235B-A22B | Alibaba | 235B MoE · 22B active | ≈ 140 GB | Spark ×2 or Studio | Apache 2.0 | Top of the open-weight table with a thinking mode; 119 languages. |
| Gemma 3 27B | 27B dense | ≈ 20 GB | Mini | Gemma terms | Best quality per gigabyte; 128K context; reads images. | |
| Mistral Small 3.2 24B | Mistral AI | 24B dense | ≈ 18 GB | Mini | Apache 2.0 | Fast, text and vision, good function calling for agents. |
| DeepSeek-R1 | DeepSeek | 671B MoE · 37B active | ≈ 390 GB | Studio | MIT | Open reasoning at frontier level; every expert must sit in memory. |
| DeepSeek-R1-Distill-Qwen-32B | DeepSeek | 32B dense | ≈ 23 GB | Mini | MIT | Most of R1's reasoning in a box the Mini can run. |
| Qwen3-32B | Alibaba | 32B dense | ≈ 23 GB | Mini | Apache 2.0 | Thinking and non-thinking in one model; the Spark sweet spot. |
| Llama 4 Scout | Meta | 109B MoE · 17B active | ≈ 66 GB | Spark | Llama 4 Community | Very long context for whole-contract and whole-manual questions. |
| Phi-4-reasoning-plus 14B | Microsoft | 14B dense | ≈ 11 GB | Mini | MIT | Small and strong on maths and logic; runs on the Mini with room to spare. |
| Qwen3-Coder-480B-A35B | Alibaba | 480B MoE · 35B active | ≈ 275 GB | Studio | Apache 2.0 | Agentic coding at the top of the open table; Studio or Station. |
| Qwen3-Coder-30B-A3B | Alibaba | 30B MoE · 3B active | ≈ 22 GB | Mini | Apache 2.0 | Fast agentic coding on a Mini or Spark. |
| Devstral Small 1.1 24B | Mistral AI | 24B dense | ≈ 18 GB | Mini | Apache 2.0 | Built for software-agent frameworks; strong on multi-file edits. |
| Qwen2.5-Coder-32B | Alibaba | 32B dense | ≈ 23 GB | Mini | Apache 2.0 | Reliable completion and repair across 40+ languages. |
| gpt-oss-20b | OpenAI | 21B MoE · 3.6B active | ≈ 13 GB | Mini | Apache 2.0 | Small, tool-using, fits beside a bigger model on the same box. |
| Qwen2.5-VL-72B | Alibaba | 72B dense | ≈ 46 GB | Spark | Qwen licence | Drawings, forms and charts; reads tables and locates parts on a page. |
| Qwen3-VL-30B-A3B | Alibaba | 30B MoE · 3B active | ≈ 22 GB | Mini | Apache 2.0 | Newer vision stack for long documents and video; fits the Mini. |
| Llama 3.2 90B Vision | Meta | 90B dense | ≈ 56 GB | Spark | Llama 3.2 Community | Photos and scans with the Llama tooling you already have. |
| Granite-Docling 258M | IBM | 0.26B | ≈ 1 GB | Mini | Apache 2.0 | Turns scanned pages and PDFs into structured text, tables and formulas; the OCR workhorse. |
| olmOCR 7B | Allen AI | 7B dense | ≈ 6 GB | Mini | Apache 2.0 | Document OCR tuned on real PDFs; fast on the Mini. |
| Jais family (up to 70B) | G42 · MBZUAI · Inception | 70B dense | ≈ 44 GB | Mini (at the limit) | Apache 2.0 | Arabic-first and trained in the UAE; the natural default for Gulf customers. |
| Falcon-H1 34B | TII, Abu Dhabi | 34B hybrid | ≈ 22 GB | Mini | Falcon LLM licence | Hybrid Mamba-Transformer, multilingual including Arabic; efficient on long context. |
| Falcon Arabic 7B | TII, Abu Dhabi | 7B dense | ≈ 6 GB | Mini | Falcon LLM licence | Native Arabic data with dialects; small enough for every tier. |
| ALLaM-7B | SDAIA, Saudi Arabia | 7B dense | ≈ 6 GB | Mini | ALLaM licence | Arabic and English, built for government and enterprise use in the Kingdom. |
| Qwen3-235B-A22B | Alibaba | 235B MoE · 22B active | ≈ 140 GB | Spark ×2 or Studio | Apache 2.0 | 119 languages with strong Arabic; the big-model option for mixed-language teams. |
| Qwen3-Embedding-8B | Alibaba | 8B | ≈ 6 GB | Mini | Apache 2.0 | Top of the multilingual embedding table; 100+ languages including Arabic. |
| Qwen3-Reranker-8B | Alibaba | 8B | ≈ 6 GB | Mini | Apache 2.0 | Re-orders the top hits so the answer cites the right page. |
| BGE-M3 | BAAI | 0.57B | ≈ 2 GB | Mini | MIT | Dense, sparse and multi-vector retrieval in one small model; 100+ languages. |
| bge-reranker-v2-m3 | BAAI | 0.57B | ≈ 2 GB | Mini | Apache 2.0 | The light reranker for high-volume document sets. |
| nomic-embed-text-v2-moe | Nomic | 0.5B MoE | ≈ 2 GB | Mini | Apache 2.0 | Multilingual embeddings with adjustable sizes for cheap storage. |
| Whisper large-v3 | OpenAI | 1.6B | ≈ 4 GB | Mini | MIT | Meeting and call transcription in 99 languages, Arabic included. |
| Parakeet-TDT 0.6B v3 | NVIDIA | 0.6B | ≈ 2 GB | Mini | CC-BY-4.0 | Very fast transcription with timestamps across 25 European languages. |
| Canary-1B-Flash | NVIDIA | 1B | ≈ 3 GB | Mini | CC-BY-4.0 | Transcribe and translate across English, German, French and Spanish. |
| Kokoro-82M | Hexgrad | 0.08B | ≈ 1 GB | Mini | Apache 2.0 | Natural text-to-speech for assistants and read-backs. |
| Chatterbox | Resemble AI | 0.5B | ≈ 2 GB | Mini | MIT | Expressive text-to-speech with voice control; watermarked output. |
| Llama Guard 4 12B | Meta | 12B dense | ≈ 9 GB | Mini | Llama 4 Community | Classifies prompts and answers against a hazard taxonomy; text and images. |
| Llama Prompt Guard 2 86M | Meta | 0.09B | ≈ 1 GB | Mini | Llama 4 Community | Catches prompt injection and jailbreak attempts before they reach the model. |
| Granite Guardian 3.3 8B | IBM | 8B dense | ≈ 6 GB | Mini | Apache 2.0 | Risk detection for RAG: groundedness, relevance, harmful content. |
| ShieldGemma 2 4B | 4B | ≈ 3 GB | Mini | Gemma terms | Image safety classification for Vision Chat uploads. | |
| NeMo Guardrails + Nemoguard 8B | NVIDIA | 8B dense | ≈ 6 GB | Mini | Apache 2.0 · NVIDIA Open Model | Policy rails around every product: content safety and topic control. |
Memory is an estimate: parameters × 0.56 bytes at 4-bit plus working context; mixture-of-experts models load every expert, so the total count is what matters. "Smallest DeepSilo" leaves room for the knowledge base and a second small model. Licences are summarised; read the model card before you ship. Models listed as of October 2026.
Your AI, the Periscope AI plane, compute, a sealed network and operations: all inside one environment you own.
Assistants, retrieval over your documents, agents with guardrails. Open-weight models (Llama, Mistral, Qwen, Gemma, DeepSeek; Falcon and Jais for Arabic) or your own fine-tunes.
Who asked what, logged for the compliance file.
Model gateway and sensitivity router · agent identity and tool policy · MCP and skill registry · signed models and data (AI-BOM) · evaluation gates · audit trail.
Every model and dataset is signed and versioned before it runs.
NVIDIA DGX Spark or DGX Station, Mac Studio with M3 Ultra, or an AMD Ryzen AI Max+ mini PC for the smallest teams. Rack and hosted options for enterprises.
Fully air-gapped builds for Spark, Station and Rack; updates arrive on signed media.
Its own segment behind a WatchGuard Firebox · network detection and response watching east-west · endpoint protection on every host · zero-trust access for people and admins, no VPN · cloud posture watched on the SaaS side.
Nothing leaves at runtime; read-only connectors to the systems you name.
24/7 detection and response · monthly security and usage report · scheduled, signed model updates · build, operate, transfer with the runbooks.
Your team takes the keys with the runbooks, or we keep running it.
Size it in a minute. This is an estimate; the written sizing follows within 24 hours.
Latency, privacy and predictability usually decide before the maths does. The maths is here so you can see it.
Monthly saving is API spend minus the operate fee. Hardware is yours at the end; the operate fee covers monitoring, updates and the monthly report. Taxes and shipping extra.
What happens next, from the first demo to the day your team takes the keys.
Twenty minutes on a real appliance, your questions, your kind of documents.
Tier, fixed fee, operate fee, what ships, what we need from you.
One signature. Hardware ordered; the sealed build starts in the lab.
Installed, documents indexed, five products on, first monthly report scheduled.
Monitoring, signed model updates, usage and security report every month.
Your team takes the keys with the runbooks, or we keep running it. Your choice.
Don't see your question here? Contact us and we'll answer it directly.
Send the form and we reply within one business day with a time and, if you asked for it, the sizing in writing.
Not ready for a demo? Ask for the free Shadow AI Snapshot instead: which AI and cloud apps already hold your company data, read-only, report in 48 hours.
Thanks, . We'll email within one business day with a time that works for your team.